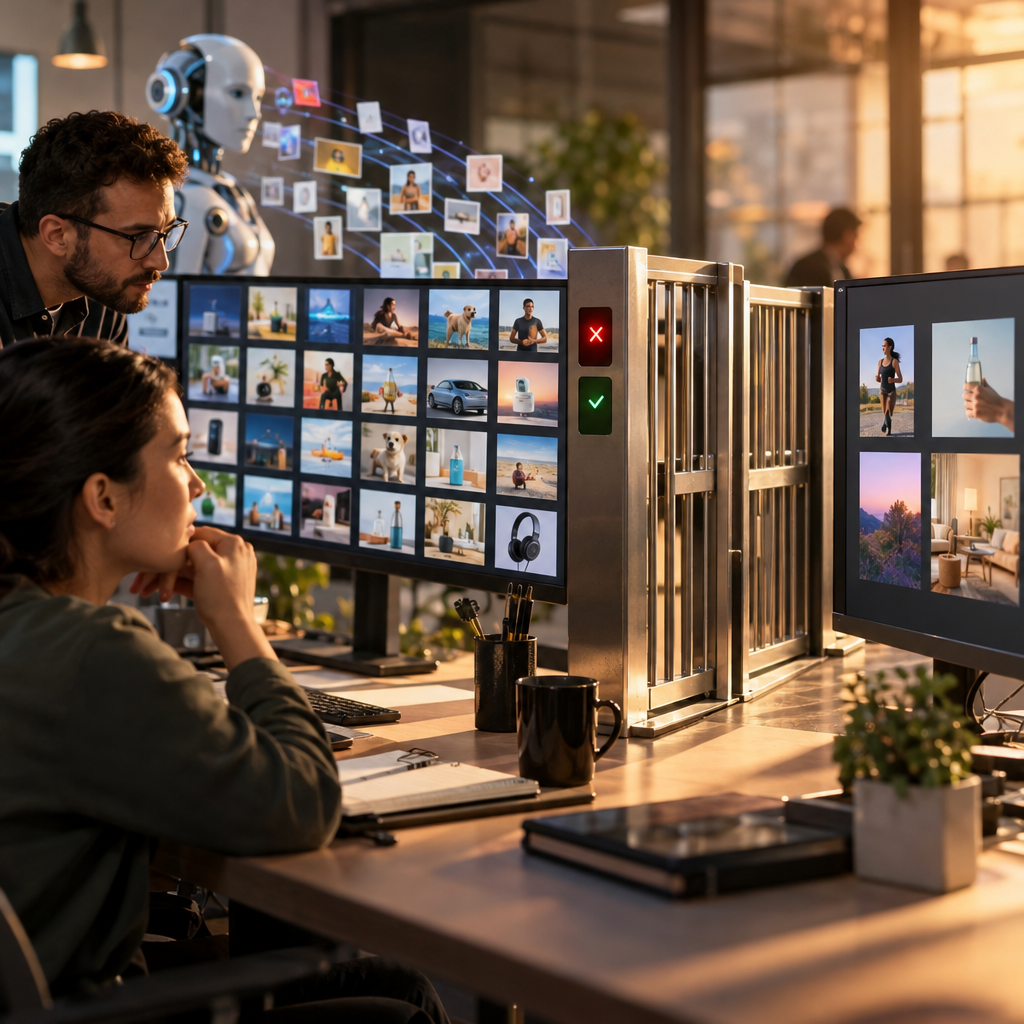
Run ten ad copy variants through an unguarded AI testing pipeline, and the odds of crowning a false winner jump from roughly 5% to 40%. That’s not a rounding error. That’s a budget decision built on noise. As generative models churn out hundreds of headline and copy variants per campaign, governance guardrails for AI A/B testing have stopped being a nice-to-have and become the difference between a defensible media plan and a compliance liability.
The Multiple Comparisons Trap Hiding Inside Every AI Testing Dashboard
Here’s the uncomfortable math most creative teams never see. When we test multiple hypotheses and treat any significant result as evidence of an effect, we create more opportunities for false positives. That’s not a theoretical concern anymore. It’s the default operating condition of any platform that auto-generates dozens of ad copy variants and reports a “winner” at the end of the week.
If you use that same alpha for 10 comparisons, the false-positive rate jumps from 5% to 40%. Now multiply that by the volume AI tools actually produce. A single product input can spin up 50 or more unique variations, and most teams aren’t running Bonferroni or Benjamini-Hochberg corrections on the back end. They’re just watching a dashboard light up green and scaling spend.
Every additional variant you let an AI system test without statistical correction is another coin flip stacked on top of the last one. At some point, “significant” stops meaning anything.
The more tests you carry out, the higher the odds of getting a false positive result just by chance, a problem known as the multiple comparisons issue. Most A/B testing tools allow you to specify the total number of comparisons or desired family-wise error rate, and the software can then automatically apply a correction when determining statistical significance. The catch: that setting has to be turned on, understood, and audited. Our earlier breakdown of why AI creative testing at scale breaks statistical significance walks through exactly where teams lose the thread between “the model says it won” and “it actually won.”
More Variants Isn’t a Strategy
Meta’s Andromeda ranking update made this collision unavoidable. According to reporting on the shift, the system began overhauling the way ads are matched to users, and one media buyer described a client brief that started as 300 creative assets but ballooned to 1,000 once it was gamed out across personas and concepts. That’s not an edge case anymore. That’s the new baseline volume for any brand running serious spend through an AI-assisted testing layer.
And yet the same reporting found real friction on the brand side. One media buyer put it plainly: “Most of our clients want to retain control because they put so much time and effort into crafting what their brand is.” That tension, volume versus control, is exactly where governance guardrails earn their keep. Volume without a correction layer gives you statistical noise dressed up as insight. Volume with proper gates gives you genuine signal at speed. The gap between those two outcomes is a governance decision, not a technology decision.
This is the same argument we made when covering why generative AI A/B testing needs guardrails, not more variants. Piling on additional copy permutations without a statistical floor doesn’t improve your odds of finding a real winner. It just inflates the denominator on your false positive math.
What Regulators Now Expect From AI-Generated Ad Copy
Governance isn’t only a statistics problem. It’s increasingly a legal exposure problem, and the rules shifted hard this year.
In the United States, the FTC established a dedicated AI enforcement unit and clarified what’s now commonly called the double disclosure requirement. The FTC now requires dual disclosure for AI-involved sponsored content, meaning two separate disclosures: the commercial relationship, that the content is an advertisement or paid partnership, and the AI involvement, that artificial intelligence was used to create or substantially modify the content. The penalty structure isn’t trivial either. Penalties reach $53,088 per violation, and each non-compliant post counts separately. Run that math across a hundred AI-generated ad variants with a missing disclosure line, and the exposure moves from annoying to board-level.
On the AI-generated copy side specifically, the agency’s own framing is clear: consumers may attribute claims to human expertise rather than AI generation when ad copy is AI-written, which is why disclosure is required. If your testing pipeline is auto-generating headline variants faster than legal can review them, you have a disclosure gap building in real time, not a hypothetical one.
Europe adds a parallel, machine-level obligation. Under the EU AI Act, providers of AI systems, including general-purpose AI systems, generating synthetic audio, image, video or text content, must ensure that AI-generated or manipulated content is marked in a machine-readable format and detectable as artificially generated or manipulated. This applies broadly across the testing pipeline, not just the final published ad. Article 50 of the AI Act applies as from 2 August 2026, with a limited grace period for the marking and detection obligation extending to 2 December 2026 for systems already on the market. If any of your creative stack touches EU audiences, that timeline is already live.
The practical takeaway: disclosure can’t be a post-launch checklist item. It has to be built into the same pipeline that generates and tests the copy in the first place, which means your tagging and classification system matters as much as your legal review. We’ve covered how messy tagging taxonomy quietly wrecks AI campaign picks, and the same mess that confuses your creative-selection algorithm will also bury your disclosure obligations if nobody’s tracking which assets are AI-generated versus AI-assisted versus human-made.
Building the Guardrail Stack: Five Gates Before Spend Scales
A workable governance framework for AI ad copy testing needs checkpoints at specific moments, not a single annual audit. Based on where the failures above actually originate, five gates cover most of the exposure:
- Pre-launch statistical design. Set your correction method (Bonferroni for strict control, Benjamini-Hochberg for a more balanced false discovery rate) before the test goes live, not after you see a result you like. Most teams overcorrect and end up with tests that never reach significance, so there’s a sweet spot between being too trigger-happy and being paralyzed by statistical rigor.
- Disclosure classification at generation. Every AI-touched asset gets tagged at the moment it’s created: fully AI-generated, AI-assisted, or human-authored. This is the only way to keep pace with double disclosure requirements without a manual review bottleneck.
- Bias and claims review before scale. AI copy generators trained on broad ad corpora can replicate skewed language patterns or unsubstantiated claims at volume. This is where a structured bias audit before AI marketing content launches earns its place in the workflow, catching issues before they’re baked into a hundred variants.
- Stopping rules, not vibes. Repeatedly checking test results for the same KPI and stopping the test once a significant result is found is a textbook case of multiple comparisons that significantly increases the likelihood of false discoveries. Define your sample size and test duration up front, and don’t let a dashboard refresh talk you into an early call.
- Spend-scaling sign-off. No AI-selected “winner” moves to budget scaling without a named human approval, logged with the statistical basis for the decision. This closes the loop between AI decisioning engines and the guardrails needed before scaling spend that we’ve flagged elsewhere.
None of these gates require slowing the creative pipeline to a crawl. They require deciding, in writing, who checks what and when, before the AI starts generating variant number one.
Who Signs Off When the Algorithm Picks the Winner?
This is the question that trips up most governance frameworks on paper. Everyone agrees a human should review AI-generated ad copy decisions. Almost nobody specifies which human, at which threshold, with what authority to pause a test.
Build an ownership matrix instead of a policy statement. Marketing ops owns the statistical correction settings and sample size calculations. Legal or compliance owns the disclosure classification and sign-off on anything touching regulated claims (health, finance, sustainability). The brand or creative lead owns a veto on tone and voice regardless of what the algorithm reports as a winner. And someone, named specifically, owns the kill switch: the authority to pause a scaling decision if the underlying data looks thin, even if the dashboard says “significant.”
A test shouldn’t be called complete based on statistical significance alone; sample size needs to be calculated and reached first. Put that rule in writing, assign it to a role, and the governance conversation stops being theoretical the first time an AI testing tool tries to declare a winner after three days and 40 conversions.
Start with one guardrail this quarter: require a named sign-off and a documented statistical correction before any AI-tested ad copy variant moves from test budget to scaled spend. Everything else in a mature governance framework builds on that single checkpoint.
FAQs
What is the multiple comparisons problem in AI ad copy testing?
It’s the statistical reality that running many variant comparisons at once inflates the chance of a false positive. Testing with 10 comparisons at a standard significance threshold can push the false-positive rate from 5% up to 40%. AI tools that generate dozens of copy variants per campaign hit this threshold routinely without anyone noticing.
Do AI-generated ad copy variants require FTC disclosure?
Yes, under current guidance. Artificial intelligence used to create or substantially modify advertising content must be disclosed, a requirement the FTC added as a new layer on top of existing sponsorship disclosure rules. This applies to AI-written headlines and body copy, not just synthetic images or video.
How does the EU AI Act affect AI ad copy testing pipelines?
Under Article 50, providers of AI systems generating synthetic text content must ensure outputs are marked in a machine-readable format and detectable as artificially generated. This obligation applies as from 2 August 2026, meaning any testing pipeline touching EU audiences needs marking built in now, not retrofitted later.
What correction method should brands use for AI A/B testing at scale?
It depends on risk tolerance. Bonferroni correction is the most conservative option, while the Benjamini-Hochberg procedure offers a more balanced approach that controls the false discovery rate rather than the family-wise error rate. Teams running high creative volume with lower individual stakes per variant often lean toward Benjamini-Hochberg to avoid losing all statistical power.
Who should own governance for AI-generated ad copy testing inside a brand or agency?
Ownership should be split by function rather than centralized in one team: marketing ops for statistical settings, legal or compliance for disclosure classification, and a named decision-maker with explicit authority to pause scaling if a result looks statistically thin despite showing as significant on a platform dashboard.
Top Influencer Marketing Agencies
The leading agencies shaping influencer marketing in 2026
Agencies ranked by campaign performance, client diversity, platform expertise, proven ROI, industry recognition, and client satisfaction. Assessed through verified case studies, reviews, and industry consultations.
Moburst
-
2
The Shelf
Boutique Beauty & Lifestyle Influencer AgencyA data-driven boutique agency specializing exclusively in beauty, wellness, and lifestyle influencer campaigns on Instagram and TikTok. Best for brands already focused on the beauty/personal care space that need curated, aesthetic-driven content.Clients: Pepsi, The Honest Company, Hims, Elf Cosmetics, Pure LeafVisit The Shelf → -
3
Audiencly
Niche Gaming & Esports Influencer AgencyA specialized agency focused exclusively on gaming and esports creators on YouTube, Twitch, and TikTok. Ideal if your campaign is 100% gaming-focused — from game launches to hardware and esports events.Clients: Epic Games, NordVPN, Ubisoft, Wargaming, Tencent GamesVisit Audiencly → -
4
Viral Nation
Global Influencer Marketing & Talent AgencyA dual talent management and marketing agency with proprietary brand safety tools and a global creator network spanning nano-influencers to celebrities across all major platforms.Clients: Meta, Activision Blizzard, Energizer, Aston Martin, WalmartVisit Viral Nation → -
5
The Influencer Marketing Factory
TikTok, Instagram & YouTube CampaignsA full-service agency with strong TikTok expertise, offering end-to-end campaign management from influencer discovery through performance reporting with a focus on platform-native content.Clients: Google, Snapchat, Universal Music, Bumble, YelpVisit TIMF → -
6
NeoReach
Enterprise Analytics & Influencer CampaignsAn enterprise-focused agency combining managed campaigns with a powerful self-service data platform for influencer search, audience analytics, and attribution modeling.Clients: Amazon, Airbnb, Netflix, Honda, The New York TimesVisit NeoReach → -
7
Ubiquitous
Creator-First Marketing PlatformA tech-driven platform combining self-service tools with managed campaign options, emphasizing speed and scalability for brands managing multiple influencer relationships.Clients: Lyft, Disney, Target, American Eagle, NetflixVisit Ubiquitous → -
8
Obviously
Scalable Enterprise Influencer CampaignsA tech-enabled agency built for high-volume campaigns, coordinating hundreds of creators simultaneously with end-to-end logistics, content rights management, and product seeding.Clients: Google, Ulta Beauty, Converse, AmazonVisit Obviously →