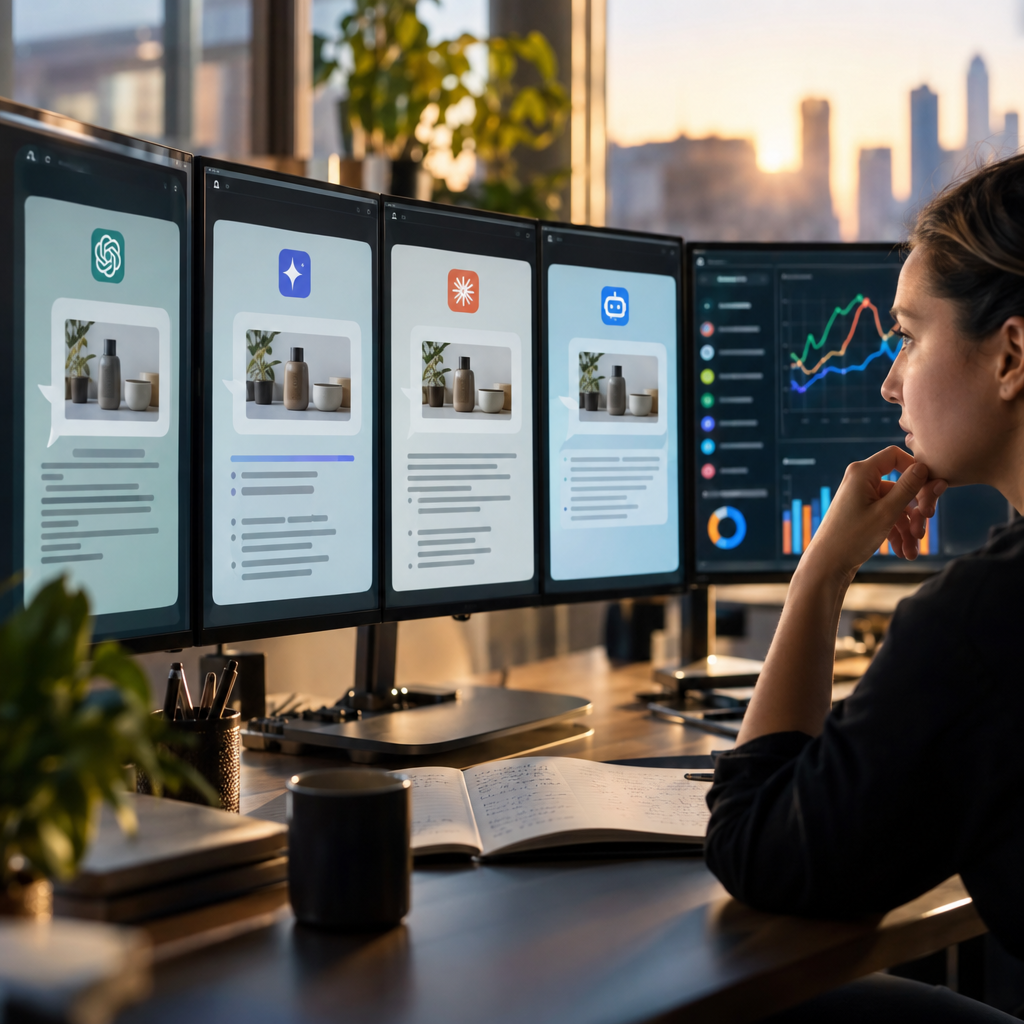
Ask ChatGPT, Claude and Gemini the same question about your brand and you’ll likely get three different answers, sometimes contradicting each other on pricing, reputation, or even whether your company still exists. That inconsistency isn’t a glitch. It’s the new reality of AI reputation management, and most brand teams still treat it like a side project instead of a core monitoring discipline.
Marketers spent a decade mastering search rank tracking. Now the ground has shifted again. Large language models don’t return a ranked list of links, they synthesize an answer and present it as fact. If that answer is wrong, outdated, or unflattering, there’s no featured snippet to dispute and no meta description to rewrite. There’s just a model’s internal representation of your brand, built from whatever it scraped, trained on, or retrieved at query time.
Why One Chatbot Audit Isn’t Enough
Here’s the uncomfortable truth: a single spot check in ChatGPT tells you almost nothing about how your brand shows up across the broader AI ecosystem. Each model has its own training data cutoff, its own retrieval behavior, and its own tone. Gemini leans heavily on Google’s indexed web and often surfaces recent news. Claude tends to be more conservative and will sometimes decline to make claims it can’t verify. ChatGPT, especially with browsing enabled, blends training knowledge with live search results.
That means a factual correction you issue today might reach Gemini’s answers within weeks, while Claude continues to cite the outdated version for months because its training data hasn’t refreshed. Brands that only monitor one model are flying blind on the other two.
Treating ChatGPT as a proxy for “AI search” is like treating one browser’s cache as the entire internet. Each model has a different memory, different sources, and a different appetite for risk.
This is the same measurement gap that’s reshaping influencer attribution. Our earlier coverage on how brand understanding replaces rank as the dominant AI search metric makes a similar point: the old scoreboard doesn’t apply anymore, and brands need new instrumentation to know where they actually stand.
How Brand Answers Diverge Across Models
Run the same prompt set across all three platforms and patterns emerge fast. Pricing claims drift. Product comparisons favor whichever competitor has more structured data (think schema markup, Wikipedia entries, G2 reviews) feeding the model. Reputation summaries sometimes surface years-old controversies as if they happened last quarter, because the model has no concept of recency unless the query explicitly triggers a live search.
There’s also a subtler issue: models hallucinate confidently. A brand might get described as “known for sustainability practices” with zero evidence to back it up, or conversely get flagged for a controversy that never actually happened, often confused with a similarly named company. Neither scenario shows up in a traditional media monitoring dashboard, which is exactly why legacy social listening tools fall short here.
This divergence connects directly to how buying decisions get made. Our analysis of how company information shapes AI product recommendations found that structured, consistent data across the web materially changes whether a model recommends your product at all. If the inputs are messy, the outputs will be too, and that inconsistency compounds across every model you haven’t audited.
The Citation Problem
Unlike traditional search, AI answers often cite sources, but inconsistently. ChatGPT might pull from a five-year-old blog post. Gemini might cite your own press release accurately. Claude might offer no citation at all and simply state a claim as fact. Brands need to know which sources each model trusts for their category, because that’s where correction efforts should concentrate.
Building a Cross Model Monitoring Framework
A usable framework doesn’t need to be complicated. It needs to be repeatable, documented, and tied to action. Here’s a structure that works for mid-size and enterprise brand teams alike:
- Define a fixed prompt library. Build 20 to 40 prompts covering brand description, product comparisons, pricing, leadership, controversies, and “best of” category questions. Reuse the exact same prompts every cycle so results are comparable over time.
- Run prompts across all three models monthly. Manual testing works for small teams. Larger organizations should use a platform built for this, which we’ll cover below.
- Score responses on accuracy, sentiment, and completeness. A simple rubric (accurate/outdated/wrong, positive/neutral/negative, mentions competitor or not) is enough to spot trends without overengineering the process.
- Track citation sources. Note exactly what each model references. This tells you where to focus correction efforts, whether that’s updating a Wikipedia entry, refreshing a press page, or pitching a journalist for fresh coverage.
- Route findings to the right owner. Factual errors go to comms. Competitive positioning gaps go to product marketing. Compliance risks go to legal. Nothing kills a monitoring program faster than reports nobody acts on.
This mirrors the discipline already applied to influencer vetting. The same rigor described in compliance-first creator program vetting applies here: you can’t manage what you don’t systematically check, and ad hoc spot checks create false confidence.
What to Do When the Models Get It Wrong
Correcting an AI model’s answer is slower and less direct than correcting a search result. You can’t submit a reconsideration request the way you might with Google. Instead, correction happens indirectly, by strengthening the signals models pull from.
Practical moves that actually shift model outputs over time:
- Publish clear, structured facts on owned properties (pricing pages, FAQ pages, press rooms) using schema markup where possible.
- Keep third-party reference sources current, including Wikipedia, Crunchbase, and industry databases that models frequently cite.
- Pursue fresh, high-authority coverage when a factual error is widespread, since models weight recent, reputable sources more heavily during retrieval.
- Use feedback mechanisms directly within ChatGPT, Claude and Gemini when available. These don’t guarantee a fix, but they feed into model improvement pipelines.
None of this works overnight. Model retraining cycles and retrieval index updates operate on their own schedules, not your PR crisis timeline. That’s the uncomfortable part of this discipline: you’re managing exposure, not flipping a switch.
AI reputation management isn’t about instant fixes. It’s about reducing the half-life of bad information across every model your customers are actually using.
This echoes a broader trend we’ve tracked around trust in AI-generated outputs. Our piece on why marketers use AI widely but rarely trust it without review makes clear that human verification remains the backstop, whether you’re reviewing AI-drafted content or auditing how a model describes your company.
Tools and Cadence: Operationalizing the Work
Several platforms now specialize in tracking brand visibility and sentiment across LLMs, often marketed under terms like “AI search optimization” or “generative engine optimization.” Evaluate any vendor on three criteria: does it query all three major models (not just ChatGPT), does it track citation sources, and does it export data your team can actually act on rather than a vanity dashboard.
For teams without budget for a dedicated platform, a manual quarterly audit using the prompt library approach above is better than nothing. Pair it with existing tools like Sprout Social for traditional sentiment tracking, and use Statista or eMarketer data to benchmark how fast AI assistant usage is growing in your category, which helps justify budget for more frequent monitoring.
Cadence matters more than tooling sophistication. Monthly checks catch drift before it calcifies into a widely cited “fact.” Quarterly checks are the bare minimum for low-risk categories. Anything slower and you’re relying on luck.
Compliance teams should also loop in legal, particularly around claims an AI model might attribute to your brand that you never actually made. This isn’t hypothetical: regulators are paying attention to AI-generated claims and endorsements, and the FTC has signaled that misleading AI outputs attributed to a brand can carry the same liability as traditional advertising claims.
If your organization already runs structured measurement for influencer and content ROI, extend that same rigor here. The methodology described in AI visibility measurement for influencer ROI applies almost directly: track mentions, score accuracy, tie findings to revenue or risk, and report on a fixed cycle rather than reacting only when something breaks.
Next Step
Start small: build a 20-prompt library this week, run it across ChatGPT, Claude and Gemini, and score the results before your next brand or comms meeting. The gap between what you assume these models say about your brand and what they actually say is usually bigger than you expect, and it only gets harder to close the longer you wait.
Frequently Asked Questions
What is AI reputation management?
AI reputation management is the practice of monitoring, scoring, and correcting how large language models like ChatGPT, Claude and Gemini describe a brand, including factual accuracy, sentiment, and competitive positioning in generated answers.
Why do ChatGPT, Claude and Gemini give different answers about the same brand?
Each model has a different training data cutoff, different retrieval behavior, and different sources it trusts. Gemini often pulls from recent indexed web content, Claude tends to be more cautious about unverified claims, and ChatGPT blends training knowledge with live browsing results when enabled.
How often should brands audit their presence across AI models?
Monthly audits are ideal for brands in competitive or fast-moving categories. Quarterly audits are the minimum baseline for lower-risk categories. Waiting longer than a quarter risks letting outdated or inaccurate information become widely cited across multiple models.
Can you directly correct what an AI model says about your brand?
Not directly. Correction happens indirectly by strengthening structured data on owned properties, keeping third-party reference sources current, pursuing fresh authoritative coverage, and using in-app feedback mechanisms where available. Changes typically take weeks to months to reflect, depending on retraining and indexing cycles.
What tools help track brand mentions across multiple AI models?
Dedicated AI visibility and generative engine optimization platforms can query multiple models simultaneously and track citation sources. Teams without budget for these tools can run manual prompt audits using a fixed, repeatable question set across each model.
Top Influencer Marketing Agencies
The leading agencies shaping influencer marketing in 2026
Agencies ranked by campaign performance, client diversity, platform expertise, proven ROI, industry recognition, and client satisfaction. Assessed through verified case studies, reviews, and industry consultations.
Moburst
-
2
The Shelf
Boutique Beauty & Lifestyle Influencer AgencyA data-driven boutique agency specializing exclusively in beauty, wellness, and lifestyle influencer campaigns on Instagram and TikTok. Best for brands already focused on the beauty/personal care space that need curated, aesthetic-driven content.Clients: Pepsi, The Honest Company, Hims, Elf Cosmetics, Pure LeafVisit The Shelf → -
3
Audiencly
Niche Gaming & Esports Influencer AgencyA specialized agency focused exclusively on gaming and esports creators on YouTube, Twitch, and TikTok. Ideal if your campaign is 100% gaming-focused — from game launches to hardware and esports events.Clients: Epic Games, NordVPN, Ubisoft, Wargaming, Tencent GamesVisit Audiencly → -
4
Viral Nation
Global Influencer Marketing & Talent AgencyA dual talent management and marketing agency with proprietary brand safety tools and a global creator network spanning nano-influencers to celebrities across all major platforms.Clients: Meta, Activision Blizzard, Energizer, Aston Martin, WalmartVisit Viral Nation → -
5
The Influencer Marketing Factory
TikTok, Instagram & YouTube CampaignsA full-service agency with strong TikTok expertise, offering end-to-end campaign management from influencer discovery through performance reporting with a focus on platform-native content.Clients: Google, Snapchat, Universal Music, Bumble, YelpVisit TIMF → -
6
NeoReach
Enterprise Analytics & Influencer CampaignsAn enterprise-focused agency combining managed campaigns with a powerful self-service data platform for influencer search, audience analytics, and attribution modeling.Clients: Amazon, Airbnb, Netflix, Honda, The New York TimesVisit NeoReach → -
7
Ubiquitous
Creator-First Marketing PlatformA tech-driven platform combining self-service tools with managed campaign options, emphasizing speed and scalability for brands managing multiple influencer relationships.Clients: Lyft, Disney, Target, American Eagle, NetflixVisit Ubiquitous → -
8
Obviously
Scalable Enterprise Influencer CampaignsA tech-enabled agency built for high-volume campaigns, coordinating hundreds of creators simultaneously with end-to-end logistics, content rights management, and product seeding.Clients: Google, Ulta Beauty, Converse, AmazonVisit Obviously →