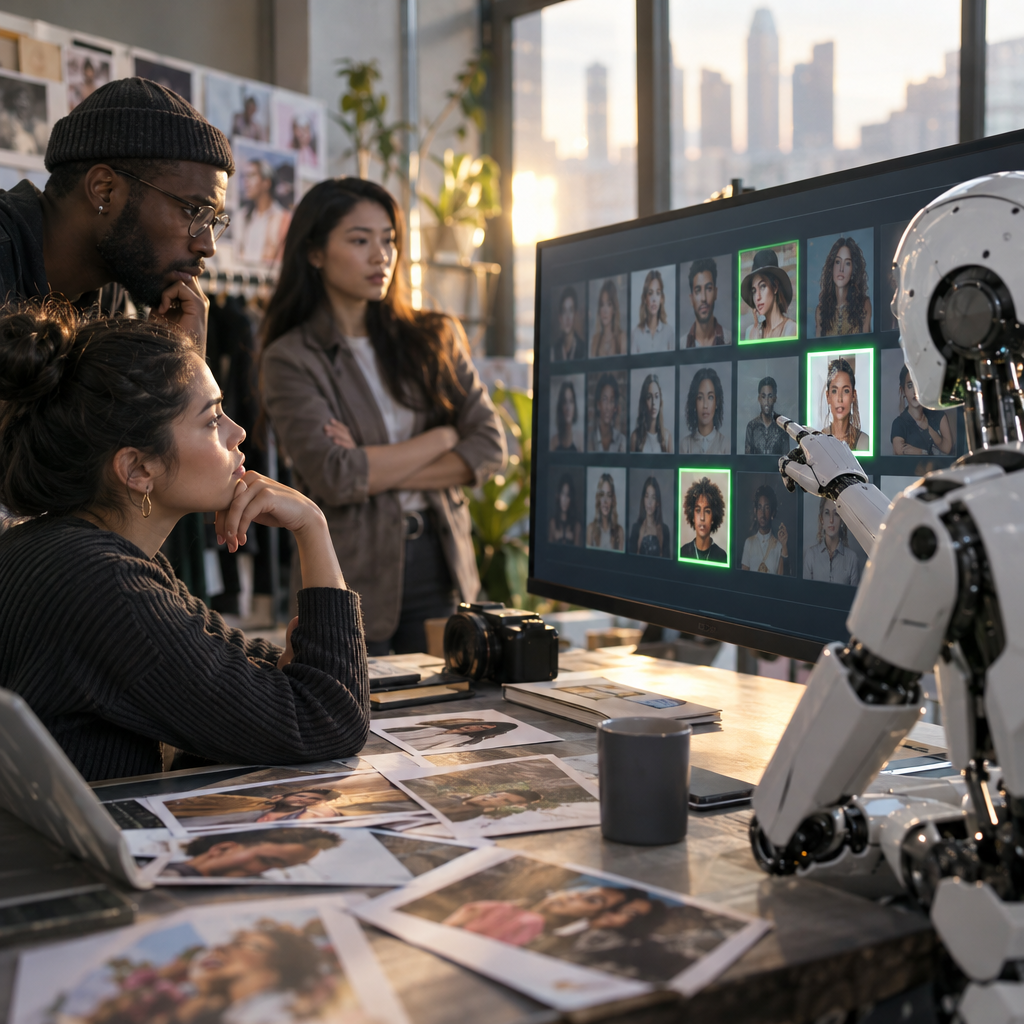
A creator-matching algorithm trained on fabricated profiles just recommended your next campaign face. Did you know that most platforms won’t tell you how much of that training data was real? Synthetic training data is becoming the quiet backbone of influencer discovery tools, and almost nobody is auditing what it’s teaching the machine to prefer.
What Synthetic Training Data Actually Is in Creator Matching
Synthetic data is artificially generated information designed to mimic real-world patterns without using actual records. In creator-matching platforms, that often means simulated engagement histories, fabricated audience demographics, or AI-generated “model” influencer profiles used to fill gaps where real data is sparse, thin, or legally restricted.
Why do it? Scale, mostly. Training a recommendation engine on millions of creator profiles is expensive and messy. Real engagement data is noisy, incomplete, and locked behind platform APIs that change their terms every quarter. Synthetic data lets vendors generate clean, labeled training sets fast. It’s cheaper than licensing data, and it sidesteps some privacy headaches tied to real audience information.
The problem is that synthetic data inherits the assumptions of whoever built the generator. If the underlying model was trained on historical campaign data that already skewed toward certain follower counts, aesthetics, or geographies, the synthetic layer doesn’t correct that. It amplifies it, then presents the output with false confidence because it looks statistically clean.
Where the Bias Creeps In
Bias in this context isn’t always about race or gender, though those are real concerns. It’s often subtler: algorithmic favoritism toward creators who resemble past “successful” campaign picks, regardless of whether that success metric was itself flawed.
- Historical bias baked into seed data. If past campaigns overindexed on mega-influencers with inflated follower counts, synthetic data generated from that history will keep recommending similar profiles, even as the market shifts toward niche and micro-creators.
- Demographic smoothing. Synthetic generators sometimes “fill in” underrepresented creator categories with averaged or composite profiles that don’t reflect any real audience, distorting match scores for entire niches.
- Engagement fabrication. Some platforms generate synthetic engagement signals to simulate what a creator’s performance “should” look like based on category benchmarks. That can mask real underperformance or, worse, real fraud.
- Feedback loop reinforcement. Once a biased match gets booked and reported as successful, that outcome often feeds back into the training set, compounding the skew over time.
A recommendation engine can’t tell the difference between a creator who performed well and a creator who matches a pattern it was told to expect. That distinction is entirely on the brand to catch.
Why Would a Platform Use Fake Data in the First Place?
It’s not nefarious by default. Most creator-matching vendors face a genuine data scarcity problem. There aren’t enough verified, labeled, cross-platform creator datasets to train a robust model purely on real observations, especially for emerging platforms or niche verticals like fintech or B2B SaaS influencers.
Synthetic data also solves a privacy problem. Regulators in the EU and UK have tightened expectations around how personal and behavioral data gets used in automated decisioning, and generating synthetic stand-ins is one way vendors try to stay compliant while still training usable models. That’s a reasonable instinct. It just needs transparency attached to it, which is where most platforms fall short.
Ask your vendor directly: what percentage of the training corpus is synthetic, and how was it validated against real outcomes? If they can’t answer, that’s your answer.
The ROI Risk Nobody’s Pricing In
Here’s the part that should worry finance teams, not just brand safety teams. If a matching algorithm consistently steers budget toward a narrow band of “safe” creator profiles because that’s what its synthetic training data rewarded, brands end up overpaying for a shrinking pool of lookalike talent while genuinely high-performing niche creators never surface in the shortlist.
This isn’t theoretical. It mirrors a pattern already documented in B2B attribution, where broken identity graphs inflate creator ROI claims without anyone noticing until the budget review. Biased matching does the same thing from the discovery side: you’re not just misreporting results, you’re misallocating spend before the campaign even launches.
There’s also a compliance angle. The FTC has made clear that deceptive endorsement practices carry real enforcement risk, and if a brand’s matching tool systematically underrepresents certain creator demographics, that starts to look like a pattern regulators and advocacy groups will eventually ask about. Nobody wants to explain an algorithmic bias problem to legal after the campaign is live.
A Vetting Checklist for Brand Teams
You don’t need a data science degree to ask the right questions. You need a short, repeatable checklist before signing a new matching platform or renewing an existing one.
- Request a data provenance summary. Ask for a written breakdown of real versus synthetic data sources in the training pipeline, updated at least annually.
- Audit match diversity over time. Pull your last four quarters of recommended creators and look for clustering around follower tiers, niches, or demographics that seems statistically improbable.
- Test with a control query. Run identical campaign briefs through two or three platforms and compare the spread of recommendations. Heavy overlap with historical picks is a red flag.
- Check for human override logs. Platforms that let strategists flag and correct biased matches, and actually track those corrections, are more trustworthy than black-box systems.
- Review third-party audits. Some vendors now publish algorithmic fairness assessments. If yours doesn’t, ask why, and ask when one is planned.
This isn’t far removed from the broader due diligence brands already apply to AI decisioning tools. The same discipline outlined in AI decisioning platform vetting applies directly here: don’t adopt a model you can’t interrogate.
Who’s Already Watching This
Procurement teams at larger agencies are starting to add synthetic data disclosure clauses into vendor contracts, the same way they’ve started requiring compliance documentation for creator program automation platforms. That’s a sensible template to borrow even if you’re a smaller brand team without dedicated legal muscle.
Industry research groups like eMarketer and Statista have both flagged growing brand concern over algorithmic transparency in influencer tools, though hard numbers on synthetic data usage specifically remain scarce because vendors aren’t required to disclose it. That silence is itself informative. Meanwhile, platforms like Meta Business have published more granular creator transparency tools over the past year, partly in response to exactly this kind of pressure.
The broader pattern tracks with what Influencers Time has covered around AI signal trust gaps putting significant budgets at risk when brands can’t verify the inputs behind automated recommendations. Creator matching is just the latest spot where that gap shows up.
What This Means for Your Next RFP
If you’re evaluating a new creator-matching or discovery platform this cycle, treat synthetic data disclosure as a baseline requirement, not a nice-to-have. Build it into your RFP scoring alongside pricing and integration capability. Vendors that balk at the question are telling you something important.
Small agencies and lean brand teams without data science resources can still apply a version of this scrutiny. Ask for sample outputs, run a manual review of the top twenty recommended creators against your actual brand fit criteria, and compare against a human-curated shortlist. If the gap is wide, the algorithm is teaching itself something you didn’t sign up for.
Frequently Asked Questions
What is synthetic training data in the context of creator-matching algorithms?
Synthetic training data refers to artificially generated information, such as simulated engagement histories or fabricated creator profiles, used to train recommendation algorithms when real-world data is limited, incomplete, or restricted by privacy rules.
Why do influencer platforms use synthetic data instead of only real data?
Real, labeled creator data is expensive to collect and often restricted by platform APIs and privacy regulations. Synthetic data lets vendors build larger, cleaner training sets faster, though it carries the risk of inheriting biases from the models that generated it.
How can synthetic data bias affect my brand’s influencer campaigns?
Biased training data can cause matching algorithms to repeatedly recommend similar creator profiles, overlook high-performing niche talent, inflate perceived fit scores, and misallocate campaign budget toward a narrower pool than the market actually offers.
What questions should I ask a creator-matching vendor about their data?
Ask what percentage of their training data is synthetic versus real, how often the model is audited for demographic or performance bias, whether they publish third-party fairness assessments, and whether strategists can flag and correct biased recommendations.
Is using synthetic data in marketing algorithms a compliance risk?
It can be, particularly if biased outputs lead to deceptive endorsement patterns or discriminatory outcomes. Regulatory bodies like the FTC and the ICO have both signaled growing scrutiny of automated decisioning tools used in marketing and advertising.
Audit one platform this quarter: pull its last twenty creator recommendations, check for clustering, and demand a data provenance answer before you renew the contract.
Frequently Asked Questions
What is synthetic training data in the context of creator-matching algorithms?
Synthetic training data refers to artificially generated information, such as simulated engagement histories or fabricated creator profiles, used to train recommendation algorithms when real-world data is limited, incomplete, or restricted by privacy rules.
Why do influencer platforms use synthetic data instead of only real data?
Real, labeled creator data is expensive to collect and often restricted by platform APIs and privacy regulations. Synthetic data lets vendors build larger, cleaner training sets faster, though it carries the risk of inheriting biases from the models that generated it.
How can synthetic data bias affect my brand’s influencer campaigns?
Biased training data can cause matching algorithms to repeatedly recommend similar creator profiles, overlook high-performing niche talent, inflate perceived fit scores, and misallocate campaign budget toward a narrower pool than the market actually offers.
What questions should I ask a creator-matching vendor about their data?
Ask what percentage of their training data is synthetic versus real, how often the model is audited for demographic or performance bias, whether they publish third-party fairness assessments, and whether strategists can flag and correct biased recommendations.
Is using synthetic data in marketing algorithms a compliance risk?
It can be, particularly if biased outputs lead to deceptive endorsement patterns or discriminatory outcomes. Regulatory bodies like the FTC and the ICO have both signaled growing scrutiny of automated decisioning tools used in marketing and advertising.
Top Influencer Marketing Agencies
The leading agencies shaping influencer marketing in 2026
Agencies ranked by campaign performance, client diversity, platform expertise, proven ROI, industry recognition, and client satisfaction. Assessed through verified case studies, reviews, and industry consultations.
Moburst
-
2
The Shelf
Boutique Beauty & Lifestyle Influencer AgencyA data-driven boutique agency specializing exclusively in beauty, wellness, and lifestyle influencer campaigns on Instagram and TikTok. Best for brands already focused on the beauty/personal care space that need curated, aesthetic-driven content.Clients: Pepsi, The Honest Company, Hims, Elf Cosmetics, Pure LeafVisit The Shelf → -
3
Audiencly
Niche Gaming & Esports Influencer AgencyA specialized agency focused exclusively on gaming and esports creators on YouTube, Twitch, and TikTok. Ideal if your campaign is 100% gaming-focused — from game launches to hardware and esports events.Clients: Epic Games, NordVPN, Ubisoft, Wargaming, Tencent GamesVisit Audiencly → -
4
Viral Nation
Global Influencer Marketing & Talent AgencyA dual talent management and marketing agency with proprietary brand safety tools and a global creator network spanning nano-influencers to celebrities across all major platforms.Clients: Meta, Activision Blizzard, Energizer, Aston Martin, WalmartVisit Viral Nation → -
5
The Influencer Marketing Factory
TikTok, Instagram & YouTube CampaignsA full-service agency with strong TikTok expertise, offering end-to-end campaign management from influencer discovery through performance reporting with a focus on platform-native content.Clients: Google, Snapchat, Universal Music, Bumble, YelpVisit TIMF → -
6
NeoReach
Enterprise Analytics & Influencer CampaignsAn enterprise-focused agency combining managed campaigns with a powerful self-service data platform for influencer search, audience analytics, and attribution modeling.Clients: Amazon, Airbnb, Netflix, Honda, The New York TimesVisit NeoReach → -
7
Ubiquitous
Creator-First Marketing PlatformA tech-driven platform combining self-service tools with managed campaign options, emphasizing speed and scalability for brands managing multiple influencer relationships.Clients: Lyft, Disney, Target, American Eagle, NetflixVisit Ubiquitous → -
8
Obviously
Scalable Enterprise Influencer CampaignsA tech-enabled agency built for high-volume campaigns, coordinating hundreds of creators simultaneously with end-to-end logistics, content rights management, and product seeding.Clients: Google, Ulta Beauty, Converse, AmazonVisit Obviously →